Fable 5.1: The New Best AI Model Is Once Again More Expensive
Set Trending Topics as a preferred source on Google.
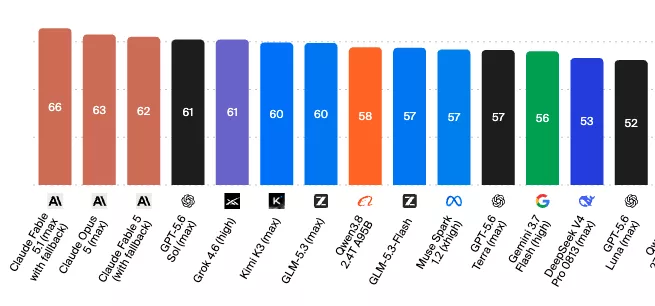
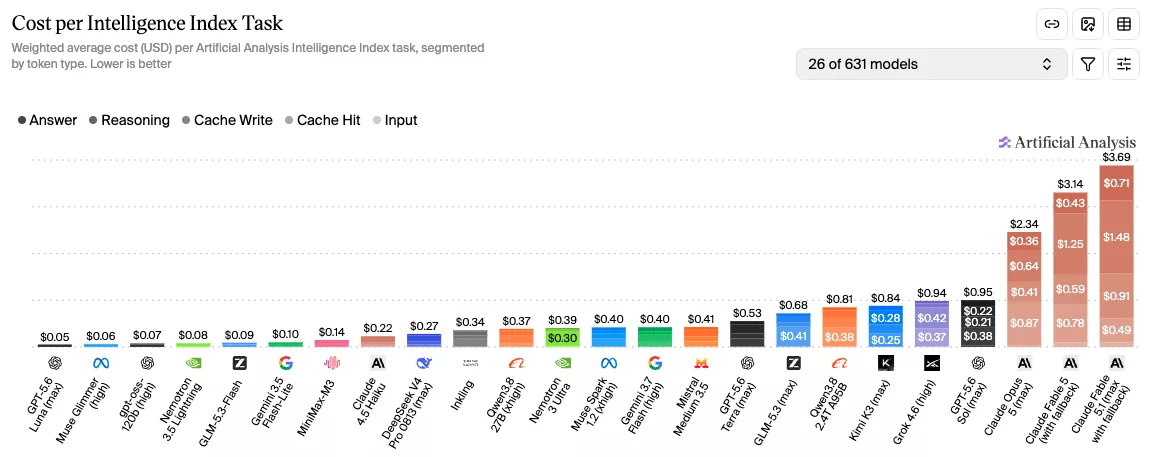
Anthropic has just introduced Claude Fable 5.1, alongside its identical sibling model Claude Mythos 5.1, which is only available through programs for vetted organizations. In the measurements of the analyst firm Artificial Analysis, Fable 5.1 takes the top spot among all models tested to date. What stands out is the gap between the savings Anthropic promises and the costs Artificial Analysis actually recorded. Anthropic is cutting the price of cache reads by 75 percent and puts the savings for typical workloads at around 25 percent compared with the previous model, rising to roughly 45 percent for heavily agentic tasks. In the Artificial Analysis measurements, however, a single task with Fable 5.1 costs about 20 percent more than with Fable 5, because the new model burns through considerably more tokens. The price cut softens that increase while leaving its direction intact.
The Highest Score Ever Recorded in the Intelligence Index
Artificial Analysis, which supported Anthropic with pre-release evaluation, measures 66 points for Fable 5.1 at the highest reasoning setting (“max”) on the Artificial Analysis Intelligence Index. According to the analysts, that is the highest score they have ever recorded, ahead of Claude Opus 5 (63), Claude Fable 5 (62), and GPT-5.6 Sol and Grok 4.6 (61 each). Against Fable 5, that is a gain of four points.
The model also collects top scores in individual disciplines. On “Humanity’s Last Exam” it reaches 59.1 percent, up from a previous best of 55.5 percent, on Terminal-Bench v2.1 it hits 91.4 percent, and on SciCode 62.0 percent. In the 𝜏³ banking scenario it gains nine points over Fable 5. Anthropic itself reports a jump from 24.7 to 52.6 percent on agentic science tasks (Terminal-Bench-Science 0.1). The Artificial Analysis tests included Anthropic’s server-side fallback, which routes safety-flagged requests to Claude Opus 4.8 or Opus 5. That fallback handled around four percent of output tokens.
Cheaper Cache Reads, Pricier Tasks
With the launch, Anthropic is lowering the price for cache reads, meaning inputs that have already been processed and stored, from one US dollar to 0.25 dollars per million tokens. The remaining prices stay where they were: 10 dollars per million input tokens, 50 dollars per million output tokens, and 12.50 dollars for cache writes. On that basis, Anthropic arrives at the 25 percent savings for typical workloads and up to 45 percent for heavily agentic tasks.
The Artificial Analysis calculation comes out differently because it factors in the higher token consumption. One task in the Intelligence Index costs 3.76 dollars with Fable 5.1 at max effort, against 3.14 dollars with Fable 5. That is 20 percent more, and 1.6 times the cost of Claude Opus 5 at 2.34 dollars. The reason is roughly 1.7 times the output token usage. The cache read cut does save about 1.40 dollars per task, concentrated in the agentic evaluations where most of the input consists of cache reads. Without it, the price would land at around 5.16 dollars.
Anyone willing to give up a single point of performance gets a better deal. At the “xhigh” setting, Fable 5.1 still scores 65 and costs 2.72 dollars per task, 1.04 dollars less than at max effort. In total, Anthropic offers five effort levels, which score between 58 and 66 points in the test and whose token consumption spans a factor of eleven (13.1 million to 143.7 million output tokens). That puts the entry-level consumption slightly above the competition: GPT-5.6 Sol at medium effort gets by on 12 million tokens.
Effectively Tied With Opus 5 on Knowledge Work
In the agentic knowledge work evaluations run by Artificial Analysis, Fable 5.1 does set new best marks (1,853 Elo on GDPval-AA v2, 1,694 on AA-Briefcase), yet the margin over Claude Opus 5 falls within the confidence interval on one benchmark and disappears entirely on the other (1,824 and 1,685 respectively). The strengths are distributed differently: Fable 5.1 leads on analytical quality and trails on how the results are presented.
Its behavior on knowledge questions is worth a look as well. In the AA-Omniscience test, Fable 5.1 attempts 93.4 percent of the questions (Opus 5: 87.8 percent) and achieves the highest accuracy ever measured at 67.2 percent. It also hallucinates more often: of the questions it got wrong, it had attempted an answer in 72.6 percent of cases, against 63.6 percent for Fable 5. The two effects cancel each other out, and the Omniscience Index score stays level with its predecessor.
Context Window, Safeguards, and Availability
The context window remains at one million tokens, with text and image inputs supported. Alongside the model, Anthropic is introducing “Enterprise Frontier Safeguards,” under which customers keep their data in cloud infrastructure they control themselves and handle any human review in house. The rollout starts in phases, and until it is ready, eligible companies can use Fable 5.1 with zero data retention. On the safety filters, Anthropic reports far fewer false alarms: in cybersecurity, around 60 percent fewer benign requests should be blocked, and the model may now be used to identify software vulnerabilities, though still not to develop exploits for them. Requests from life sciences research continue to be routed to the Opus models.
Fable 5.1 is available immediately through the Claude API as well as Amazon Web Services, Google Cloud, and Microsoft Azure. In Claude Code the model defaults to “high” effort, and in Claude Cowork and on claude.ai to “medium.”
One thing the flat rate of the Claude subscriptions leaves out is the new model itself: Claude Pro users pay extra to work with Fable 5.1. That leaves Claude Opus 5 as the best model included in the subscription. For subscribers, this matters mainly because the Artificial Analysis numbers put Opus 5 close to Fable 5.1 on agentic knowledge work anyway, at a lower cost per task.