Forget AGI, Here Comes RSI: Z.ai Says Its GLM Model Built Its Own Inference Infra
Set Trending Topics as a preferred source on Google.
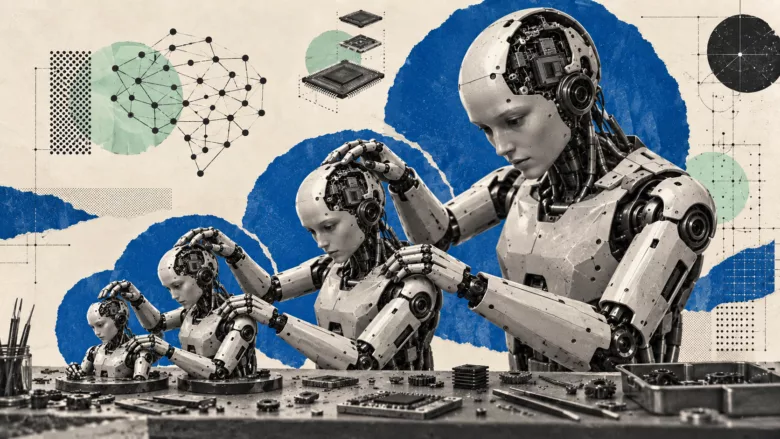
For years, the AI industry’s biggest debate has centered on AGI, or artificial general intelligence. Now another acronym is moving to the front: RSI, short for recursive self-improvement. The term describes an AI system that helps drive its own development, to the point where it could eventually design and train its successor on its own. Chinese AI company Z.ai (formerly Zhipu AI) has just published a detailed research post describing how its GLM-5.3 model played a central role in building the very infrastructure that one version of the model now runs on.
The key sentence of the post reads: “The model optimizes the system; the system runs the model.”
More Than 100,000 Chinese AI Chips
The system in question serves GLM-5.3-Flash. According to Z.ai, the company built a production-grade inference service from scratch for the model on a cluster of more than 100,000 AI accelerators made in China. All production inference for GLM-5.3-Flash is said to run on this system. Z.ai says no one had previously deployed a cluster of Chinese-made accelerators at this scale.
The company describes significant obstacles: relatively limited chip memory and bandwidth, a new model architecture, a context window of one million tokens and multimodal requests. The ecosystem was immature, kernel support was incomplete, and much of what should have been documented had to be guessed, Z.ai writes. A large share of the work was reportedly carried out by an “Infra Agent” powered by GLM-5.3.
The results, according to Z.ai: GLM-5.3-Flash went from initial model adaptation to production readiness in less than two weeks. End-to-end throughput roughly tripled compared with the initial baseline, and hardware efficiency and per-token cost reached levels comparable to mainstream Nvidia GPUs. Before launch, the model was tested anonymously as Ox-Alpha on OpenCode and OpenRouter, where it reportedly became the most-used model on both platforms within a week, processing more than 62 trillion tokens in six days. Z.ai has since confirmed that it is behind Ox-Alpha.
“Dense Feedback” as the Key Ingredient
At the core of the post is a concept Z.ai calls “dense feedback.” The underlying idea: an agent gains little from coarse signals such as “throughput dropped by 20 percent,” because they do not reveal which layer of the system is responsible. Z.ai therefore built correctness tests, runtime logs, execution traces, microbenchmarks and end-to-end metrics into the agent’s workflow, so it can test hypotheses locally, quickly and verifiably.
The company describes a clear division of labor. Engineers define objectives and system boundaries and review critical changes. The agent handles analysis, hypotheses and code changes. The experimental environment supplies the feedback.
Z.ai offers three examples:
- Numerical errors: The agent found an accuracy issue in the context parallelism path of the KDA kernel that grew worse with long contexts. According to Z.ai, the fix has been merged into the open-source project Flash Linear Attention.
- Concurrency bottleneck: In the interplay between DeepEP and Mooncake Transfer, Python’s global interpreter lock (GIL) was holding up KV cache transfers. After the fix, the performance gap between test scenarios shrank from more than 20 percent to less than 1 percent.
- Kernel optimization: The agent extracted optimization techniques from existing projects such as SGLang and DeepGEMM, distilled them into reusable “optimization skeletons” and achieved a 1.71x speedup on a decode kernel.
Z.ai Tempers Its Own Claims
Despite the bold framing, Z.ai stays cautious in its assessment. The company writes that it has not yet reached recursive self-improvement, though early forms of it are emerging. Choosing objectives, setting boundaries and assessing risk remain human responsibilities, and humans should hold that line for a long time to come, according to the post. At the same time, Z.ai says GLM-5.3 has become an indispensable daily coding partner for its entire team and is “moving steadily toward replacing us.”
For now, the claims are difficult to verify independently. The figures on throughput, development time and cluster size come solely from the company, and the post does not spell out exactly how much of the work the agent did compared with the engineers involved. The most readily verifiable element is the public code contribution to Flash Linear Attention.
The post also stands out because Z.ai has recently drawn attention mainly for the cybersecurity capabilities of its models. GLM-5.2 is said to rival Anthropic’s Mythos in this field, and in the new post the company writes that its security partners have used GLM to find thousands of vulnerabilities in real-world codebases.
Google Is Also Rumored to Have Reached RSI
Z.ai is not the only company tied to the topic. Google, which has been comparatively quiet on the new-model front lately, recently became the subject of a rumor that it has achieved RSI. The rumor traces back to a cryptic post by the AI leak account “Lyra,” which congratulated Google DeepMind with the words “huge congRatulationS Indeed!” The capital letters spell out RSI. Google has not confirmed anything, and the post named no model, research result or benchmark, as Zeniteq points out.
What is well established is that Google is investing heavily in self-improving systems. According to Reuters, the company has reshuffled its AI leadership, and co-founder Sergey Brin is reportedly pushing internally to steer DeepMind more firmly toward recursive self-improvement. Google’s AlphaEvolve system has already sped up a kernel used to train the company’s own models, slightly reducing training time. Whether these early feedback loops will turn into a self-accelerating cycle remains an open question, at Google as well as at Z.ai.